Writing· RAG permissions
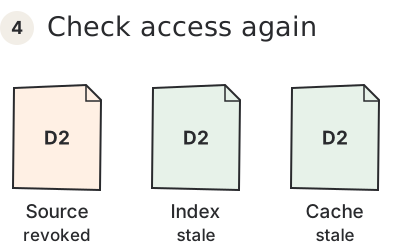
Access was revoked. What happens now?
Yesterday’s stamp cannot prove today’s permission.
Step through a permission change at the source, a stale index, and an old cached answer. Learn where current checks belong.
- RAG
Latest
The complete chronological feed across writing, projects, talks, and judging. Most recent first.
131 entries
Yesterday’s stamp cannot prove today’s permission.
Step through a permission change at the source, a stale index, and an old cached answer. Learn where current checks belong.
Securing the Agentic Tool Layer: A Runtime Defense Framework for MCP Agent Deployments
Talk and demo at CloudX 2026 on defending Model Context Protocol agents against attacks that arrive through the tools they already trust, built on ShieldMCP and the SAFE-MCP technique catalogue.
Five requested does not always mean five returned.
Move a retrieval cutoff and see why removing denied results can leave a short answer packet. Measure recall against an allowed baseline.
Trustworthy AI Agents: Test in CI, Enforce at Runtime
Talk at API:World 2026 on catching unsafe agent behaviour before release and stopping it at runtime, using policy tests, grounded-answer checks, trajectory tests, and versioned tool contracts.
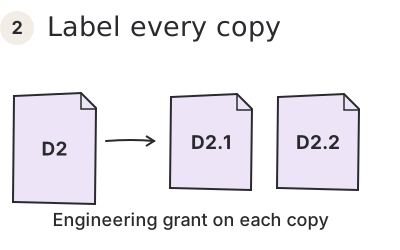
A photocopy does not acquire new readers.
Follow a restricted folder through the copy room. Preserve its permissions on every chunk and reject missing labels.
A great match is not a permission slip.
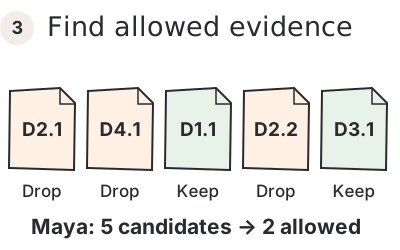
Predict how an employee’s identity changes a RAG answer, inspect the permission decision, and run the same policy yourself.
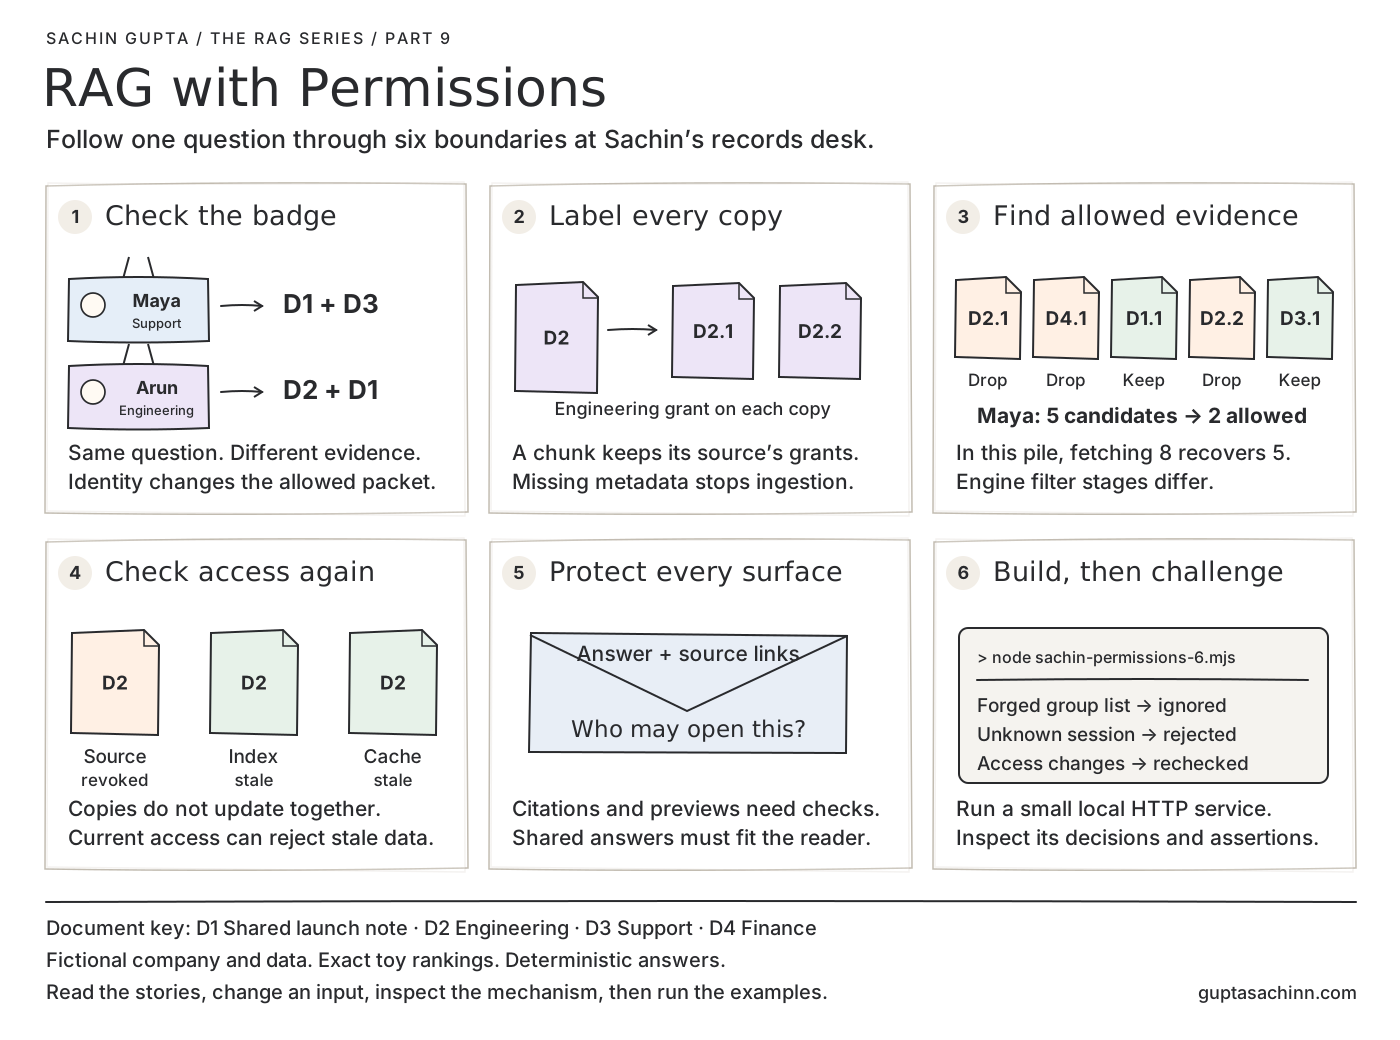
Follow the badge, the folder labels, and the briefing packet.
Six illustrated lessons on identity, document permissions, retrieval, revocation, protected responses, and a runnable local service.
Technical Program Committee member for the 2026 IEEE International Conference on Big Data (IEEE BigData 2026) in Phoenix, Arizona, reviewing two submitted papers.
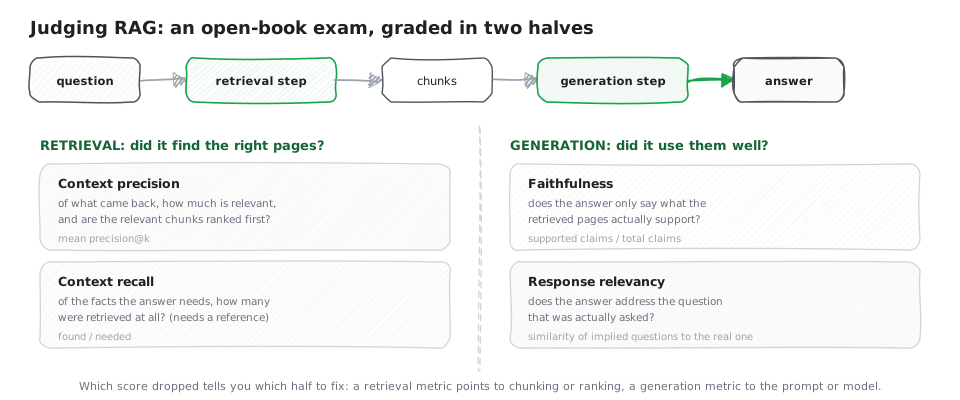
Grading a RAG answer is grading an open-book exam. Two separate questions: did it find the right pages, and did the answer actually use them.
Part eight of the RAG series. A wrong RAG answer has two possible culprits, and one number cannot tell them apart. Evaluation splits like grading an open-book exam: retrieval quality (context precision, did it bring back relevant pages and rank them first; context recall, did it miss any needed page) and generation quality (faithfulness, did the answer only say what the pages support; response relevancy, did it address the question asked). This defines a classic four-metric starting set from Ragas, each with its formula and a worked example, explains which need a ground-truth reference and which use an LLM as judge, and why an LLM-judge score is a moving target. Everyday analogies, a hand-drawn diagram, and a visualizer per metric.
Program Committee member for the 2026 IEEE International Conference on Agentic AI (IEEE ICA 2026) in Kumamoto, Japan, reviewing three submissions on agentic and multiagent systems.